FilyBase logoFilyBase
SERVERLESS INFERENCE, WITHOUT THE CHAOS

Fastest. Cheapest.
Inference.

Deploy Llama, Mixtral and your own fine-tunes on GPUs that scale to zero — and back up in milliseconds. Real endpoints, real humans behind support.
Start building — freeTry in console
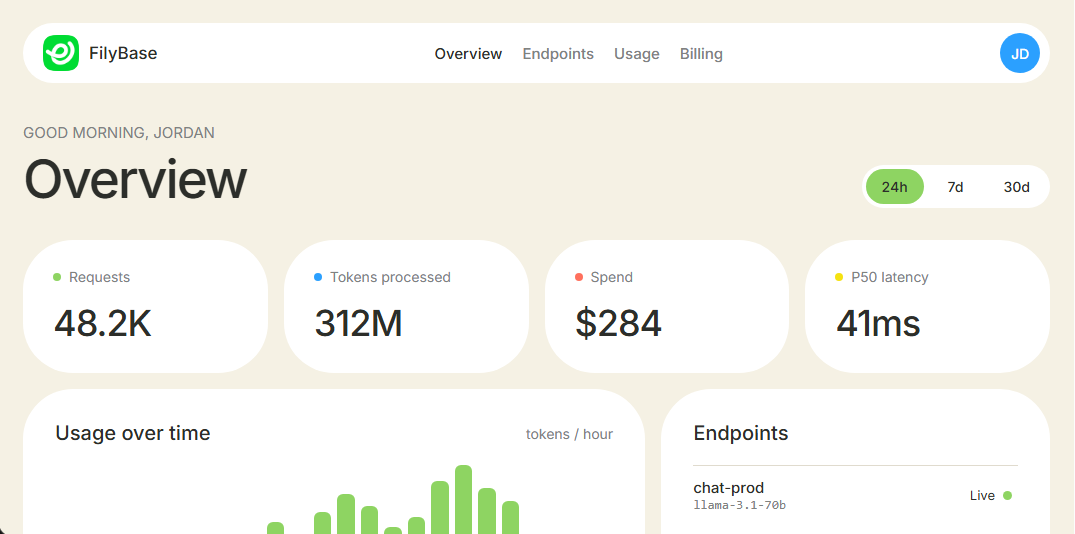
FilyBase dashboard preview

No more idle GPU bills.

One endpoint, metered per token. Traffic spikes provision capacity in seconds; quiet hours cost nothing.

See how it works
Character browsing model shelf
MODEL CATALOG

Bring any open model.

Or your own fine-tune. Every model gets an OpenAI-compatible endpoint.

Llama 3.1 70B
$0.90 / 1M tok
View →
Mixtral 8x22B
$1.20 / 1M tok
View →
Stable Diffusion 3
$0.02 / image
View →
HOW IT WORKS

Three steps to production.

1
Pick a model

Choose from the catalog or upload a fine-tune.

2
Call the API

Swap your base URL — existing SDKs keep working.

3
Scale automatically

GPUs provision in seconds; idle costs nothing.

PRICING

Pay for tokens, not idle time.

Pay as you go
$0

Metered per token · shared pool

Start free
Scale
$399/mo

Higher rate limits · priority queue

Talk to sales
Enterprise
Custom

Custom terms · dedicated support

Contact us

Ship inference in an afternoon.

DocsPrivacyTerms
© 2026 FilyBase, Inc.